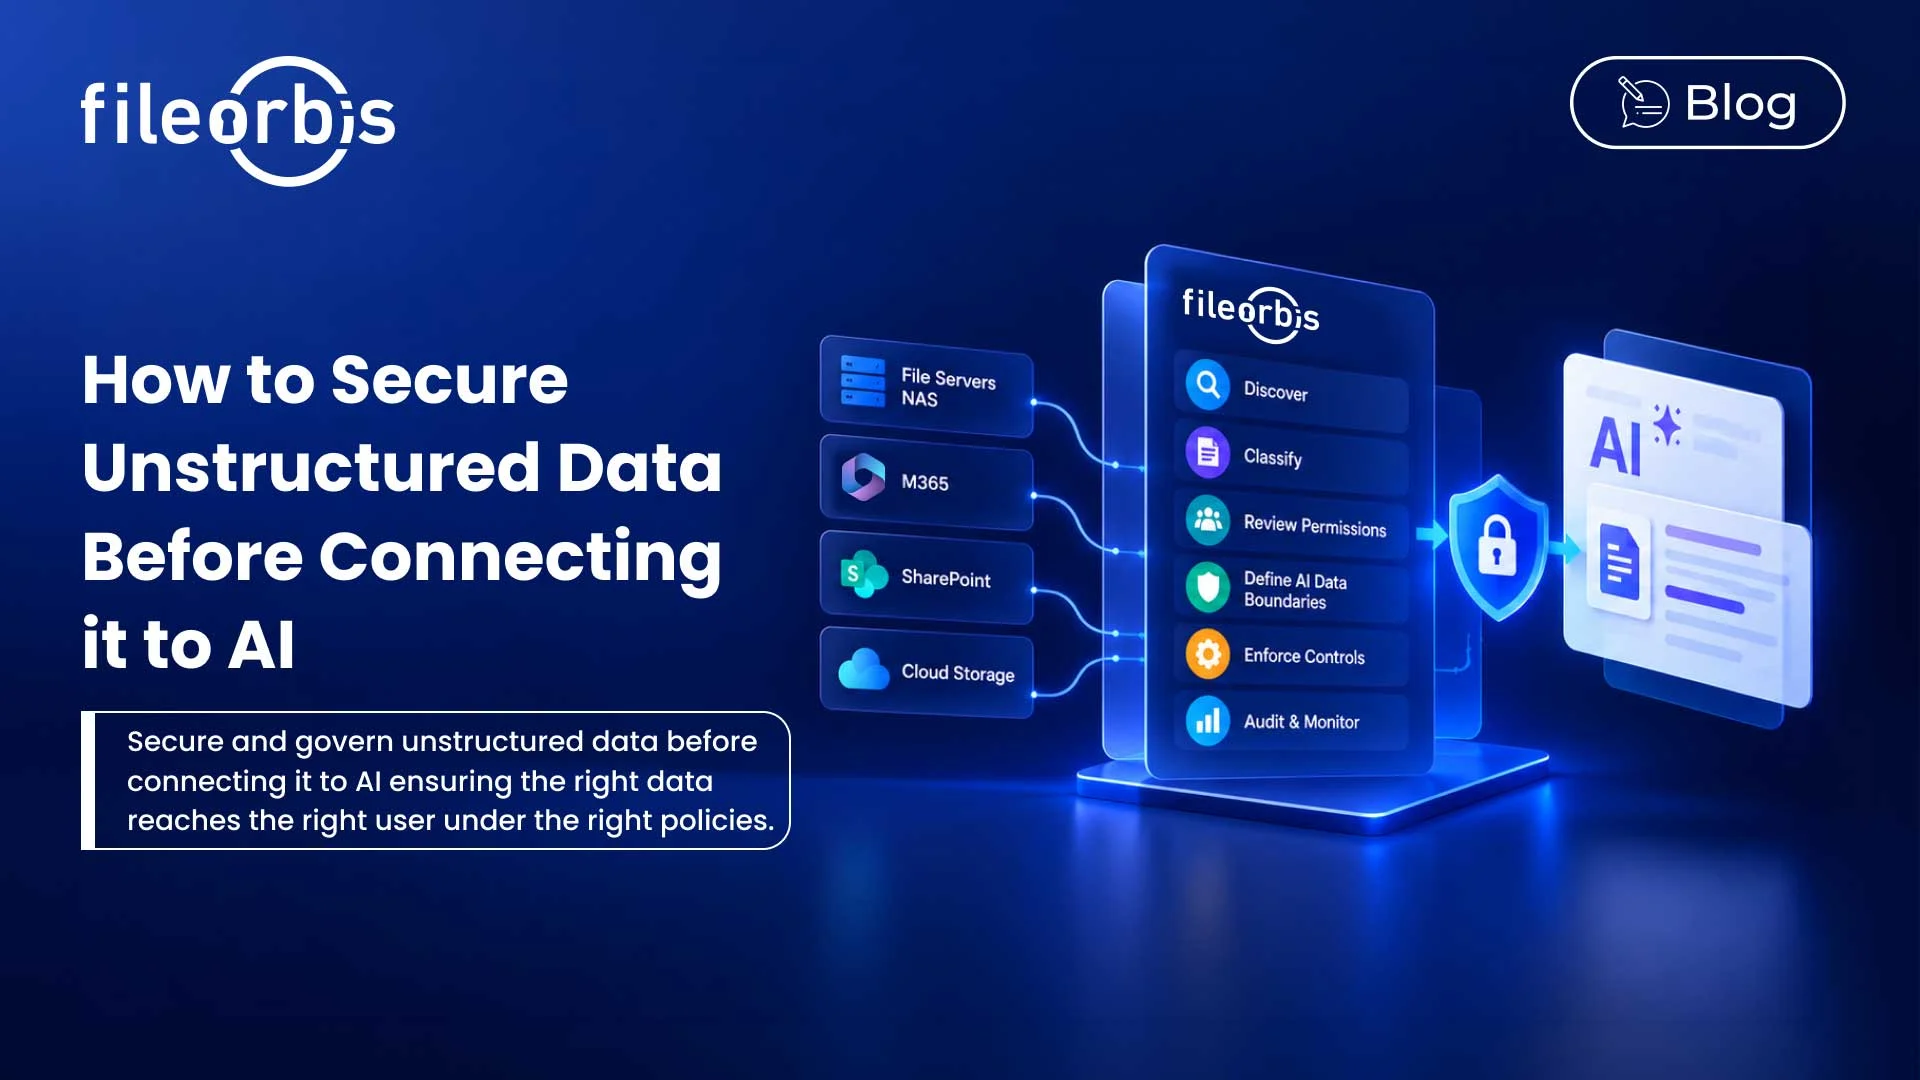
How to Secure Unstructured Data Before Connecting it to AI
Connecting enterprise files to GenAI, RAG, or AI assistants can make accessing enterprise information easier. However, it can also increase existing security vulnerabilities.
Sensitive data may be stored in inappropriate locations, permissions may be overly broad, and some repositories may contain information that should never enter the AI workflow.
Therefore, unstructured data AI security should begin before enterprise content is connected to AI.
Organizations need to understand what data they possess, who can access it, and what content should be allowed for AI to use.
Why Unstructured Data Creates Security Risks for AI
Enterprise information is distributed across file servers, NAS, M365, SharePoint, cloud storage, and legacy storage.
These environments may contain years of accumulated permissions, outdated documents, sensitive information, and uncontrolled copies
AI makes it easier to discover this content. Information that was previously difficult to find can become accessible with a simple natural language query.
Before connecting these repositories to AI, businesses should establish controls between enterprise content and AI access.
Discover the Data AI Can Access
You cannot control AI’s access to information you do not know exists.
Start by identifying repositories and files that could be part of the AI knowledge base.
This discovery should provide visibility into:
- File location and ownership
- File type and age
- Sensitive content
- Existing permissions
- Repository context
- External exposure
The goal is to understand the existence of the data before deciding what the AI should access.
Classifying Sensitive and Business Critical Content
Once content is discovered, organizations need to understand what these files contain.
Classification can identify:
- Financial information
- Human resources records
- Personal and regulated data
- Contracts and legal documents
- Intellectual property
- Credentials and other sensitive content
- Confidential business information
Organizations can then decide whether to allow, filter, restrict, anonymize, or exclude the content from AI processing.
Review Permissions Before AI Ingestion
AI should not increase excessive access.
Enterprise data repositories often accumulate outdated group memberships, inherited permissions, and unnecessarily broad access rights.
Before connecting data to AI:
- Identify excessive access
- Remove stale users and groups
- Review permissions on sensitive files
- Verify inherited permissions
- Remediate unnecessary exposure
- Enforce least privileged access
For RAG, relevance alone should not determine whether a document reaches the model. User authorization should remain part of the access decision.
Define Approved Repositories for AI
Connecting every existing repository to AI creates an unnecessarily large risk surface.
Instead, define clear AI data boundaries:
- Approved: Available for defined AI use cases
- Restricted: Requires additional controls
- Conditional: Available only under specific policies
- Excluded: Should not enter the AI pipeline
For example, an enterprise knowledge repository might be approved, while HR, legal, executive, or highly regulated content might remain restricted.
This provides AI with a controlled limit on information rather than unlimited access to the enterprise file assets.
Enforce Permissions and Content Policies During Data Retrieval with AI
Security controls should not disappear once files are indexed.
A governed RAG workflow should evaluate both user authorization and content policies when retrieving information:
- User
- Identity
- Permission Control
- Content Policy
- Retrieve
- AI
- Governed Response
Controls should apply not only to documents but also to file names, metadata, summaries, citations, and snippets.
If a user cannot access a source, AI should not reveal information from that source.
Controls should also reflect changes in the underlying repositories. Permission changes, deleted files, new classifications, and newly restricted content should affect the information that AI can retrieve.
Make AI Access Auditable
Organizations need visibility into how AI uses enterprise content.
Audit logs should help answer these questions:
- Who submitted the request?
- What content was received?
- What controls were applied?
- Which repository did it come from?
- Which AI service processed the information?
- Was sensitive content filtered or blocked?
This provides traceability for security investigations, governance, and compliance requirements.
AI Pre-Integration Security Checklist
Before connecting enterprise repositories to GenAI or RAG, verify the following:
- Repositories and sensitive data are classified and discovered.
- Sensitive content can be filtered, blocked, or anonymized.
- Excessive permissions are identified and remediated.
- Least privilege access is enforced.
- Existing permissions remain effective during retrieval
- Restricted, approved, and excluded AI data sources are defined.
- AI access and retrieval activity have been logged.
How FileOrbis Helps
FileOrbis provides a governance layer between existing enterprise repositories and AI systems.
Organizations can use FileOrbis to discover and classify enterprise files, identify sensitive data, enforce content-aware policies, analyze over access, and enforce existing permissions during AI access.
FileOrbis also enables organizations to control which content AI can access, synchronize permission changes, filter or anonymize sensitive information, and maintain audit logs.
This allows organizations to extend content-aware and permission-aware controls to enterprise AI and RAG while maintaining governance of data where it already resides, without the need for repository migration.
In Summary
Unstructured data AI security begins before the data reaches the model.
Organizations should discover and classify content, define AI data limits, remediate over access, and keep permission and content controls active during access.
The goal is simple: give AI access to the right data, for the right user, under the right policy.
Emre Demiray
Founder – FileOrbis
Subscribe to our Newsletter
About FileOrbis
Aiming to manage the user and file relationship within an institutional framework, FileOrbis is constantly being developed in order to meet different industry and customer needs in terms of file management and sharing. Since 2018, FileOrbis continues to be developed with the excitement of the first day. FileOrbis focuses on high security, rich integration, ease of use and integrated management criteria.